Claude Fable 5.2 vs GPT-6 Astra by effort level
Fable 5.2 leads GPT-6 Astra 65 to 57 at Max. At Medium it scores 56 for $3.80 per index task. Compare coding, PDF work and API pricing.
GTM Architect & Growth Operator · Now · 10 November 2026 · 6 min read
On this page
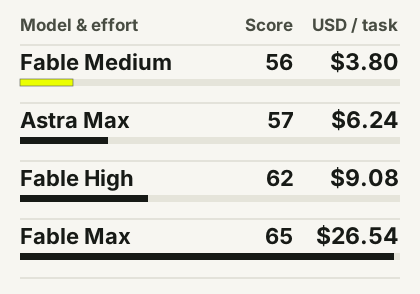
Anthropic launched Fable 5.2 on November 9. At Max, it scores 65 to GPT-6 Astra’s 57 in Artificial Analysis. It also costs $26.54 per index task against $6.24. The setting I would try first is Fable at Medium: 56 points for $3.80.
What each effort level costs
| Model and effort | Score | USD / task |
|---|---|---|
| Claude Fable 5.2 Max | 65 | $26.54 |
| Claude Fable 5.2 Xhigh | 62 | $14.83 |
| Claude Fable 5.2 High | 62 | $9.08 |
| GPT-6 Astra Max | 57 | $6.24 |
| Claude Fable 5.2 Medium | 56 | $3.80 |
| GPT-6 Astra High | 55 | $3.24 |
Artificial Analysis comparison, checked November 10, 2026. Fable runs use Anthropic’s default fallback. Cost is a weighted average per attempted index task, calculated from token use and API prices. It includes attempts that failed the task.
At Medium, Fable comes within one index point of Astra Max for 39% less per index task. At High and Xhigh it has the same rounded score, 62, for $9.08 and $14.83 respectively. I would try High before Xhigh unless the individual tasks I care about show a clear reason to pay the difference. Fable defaults to High in the API and Medium in Claude apps and Claude Code. Claude API · Claude apps and Claude Code
The lead depends on what you hand the model
| Artificial Analysis evaluation | Fable 5.2 Max | GPT-6 Astra Max |
|---|---|---|
| FrontierCode 2.0 | 48.8% | 42.4% |
| Terminal-Bench 4.0 | 59.6% | 59.1% |
| GDP.pdf | 24.2% | 31.0% |
| Terminal-Bench-Science 0.1 | 73.3% | 63.3% |
Same test suite and snapshot. FrontierCode tests changes to real open source repositories. It is a better lead for evaluating a complex patch than the overall index. On terminal work the measured difference is only half a percentage point. For workflows involving dense PDFs, Astra gets a seat in the trial.
The surrounding software can change the result. On ARC-AGI-3’s semi-private games, the best reported Standard harness scores were 81.2% for Fable and 62.7% for Astra. With the Provider Adapter, which keeps reasoning state between requests, the best observed scores were 97.7% and 99.9%. Those are best observed scores across settings in each harness. It is a good reason to test the environment you will actually ship, especially if it keeps state differently. ARC Prize: Fable · ARC Prize: Astra
The rate card and the run bill
| API spec | Fable 5.2 | GPT-6 Astra |
|---|---|---|
| Input per million tokens | $8 | $10 |
| Cached input per million | $0.20 | $1.00 |
| Output per million | $40 | $50 |
| Context window | 1M | 1.05M |
| Max output | 128K | 128K |
| Long prompt premium | Standard rates across 1M | Above 272K input: 2× input and cache, 1.5× output |
Claude specs · Claude pricing · OpenAI specs. A hypothetical request with 100K uncached input and 10K billable output costs $1.20 on Fable and $1.50 on Astra, before tools. Those fixed token counts explain the rate card. The $26.54 and $6.24 above reflect the tokens consumed in the benchmark runs.
Fable 5.2 cuts both standard rates by 20% from Fable 5.1. Anthropic reports up to 30% faster token generation than 5.1. The optional Fast mode lists at $16 input and $80 output per million and promises up to 2.5× generation speed. Both speed claims describe how fast tokens come out. For a migration or research run, measure the time to an accepted result. Launch pricing and speed claims
What the Fermat demo shows
Anthropic reports that about 1,000 Fable 5.2 agents formalized the proof of Fermat’s Last Theorem in Lean in 30 hours. The theorem already had a proof. The work here was to express it in a form a computer could check. Anthropic describes one run per model in that experiment. I would take the demo seriously as an example of work you can split up and verify, and keep it separate from the API cost comparison. Anthropic’s experiment
Anthropic also released Mythos 5.2. The underlying model and list price match Fable. Fable is available on paid Claude plans and via the API, with additional cybersecurity and biology safeguards. Direct Mythos access goes through verification programs. Anthropic’s release table uses different task sets for different labs on CyScenarioBench, so those percentages cannot establish a head-to-head winner. Launch and methodology
Anthropic’s operating system demo
In a separate coding experiment, Anthropic reports that Fable 5.2 coordinated over 1,000 agents over eight days to build a prototype operating system that boots on a laptop. The clip shows the prototype. Anthropic’s coding write-up
Where I would spend the first test budget
Give Fable Medium and Astra Max the same difficult change in a repo. Freeze the starting commit, tests, tools and time budget. Have a reviewer score the patch without seeing which model wrote it. Record how many patches pass, how much time they need in review, and the bill for every attempt. Move Fable to High only if the Medium failures look like the kind extra reasoning can fix.
For routine tickets, I would include Opus 5.5 or GPT-6.1 Sol before raising that budget. For a comparison of the tools that run the models, see Claude Code vs Codex. That article names the model versions it tested.
Continue with the daily model comparison. GPT-6.1 Sol vs Claude Opus 5.5
Questions people ask
Is Claude Fable 5.2 better than GPT-6 Astra?
Fable leads 65 to 57 at Max in Artificial Analysis Intelligence Index v5.0.1. It leads on FrontierCode 2.0, while Astra leads on GDP.pdf in that comparison.
Is Claude Fable 5.2 cheaper than GPT-6 Astra?
Fable has lower standard input and output prices. At Max it costs $26.54 per index task versus $6.24 for Astra. At Medium, Fable costs $3.80.
What is the difference between Claude Fable 5.2 and Mythos 5.2?
They share an underlying model and list price. Fable has additional safeguards for cybersecurity and biology. Direct Mythos access is gated through Anthropic’s verification programs.